Text similarity analysis
Measuring similarities and matches between sections and paragraphs.
Software capable of uncovering text similarities between text documents, which can be operated both locally and as a cloud service — for the automated identification of suspected plagiarism cases.
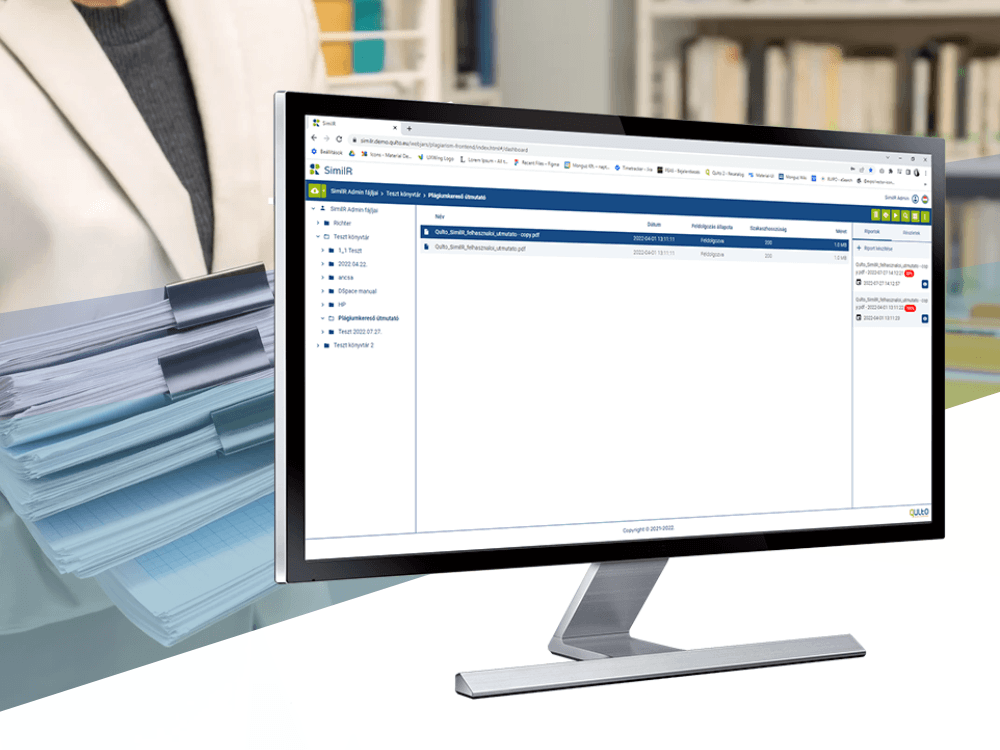
SimilR is software capable of uncovering text similarities between text documents, and it can be operated both locally and as a cloud service. Its basic task is to index, for comparison purposes, the theses held by higher education institutions and other academic content available to us.
The basis of the comparison is the measurement of similarities and matches between document sections and paragraphs. Our innovative business model also generates revenue for the cooperating content owners (institutions), based on how often their relevant documents are used.
Machine comparison of documents for the automated identification of suspected plagiarism cases — the software generates a preliminary report on cases above the tolerance threshold, which can be used in evaluation and decision-making processes.
The document to be checked for plagiarism can be uploaded on a central web interface, and the same interface is also used to view the results.
It allows several institutional and individual users to run analyses at the same time, and to change the analysis and filtering parameters individually — taking into account the genre, form and subject-matter characteristics of the texts.
We process institutional content locally, thus avoiding the copyright problems typical of plagiarism checkers — Hungarian-language documents protected by copyright law are not placed on foreign servers or in the ownership of foreign companies.
Measuring similarities and matches between sections and paragraphs.
Institutional content is processed locally, without copyright risk.
Upload and viewing of results on a single central interface.
Individual filtering settings according to the genre and form of the texts.
Simultaneous analyses for several institutional and individual users.
Analysis on individual, shared and web corpora alike.
Preliminary report on suspected plagiarism cases above the tolerance threshold.
Cooperating content owners can also earn revenue from the use of their documents.
Primarily the theses of higher education institutions and other academic text content.
It can be operated both locally and as a cloud service, according to the institution's needs.
We process institutional content locally, so protected documents are not placed on foreign servers.
Yes, the analysis and filtering parameters can be set individually to suit the genre, form and subject-matter characteristics of the texts.
Our colleagues will gladly show you how the product works — leave your contact details and we will get in touch. Fields marked with an asterisk are required.